In a separate lawsuit against Meta, it alleged the authors’ books were accessible in datasets Meta used to train its LLaMA models….reports Asian Lite News
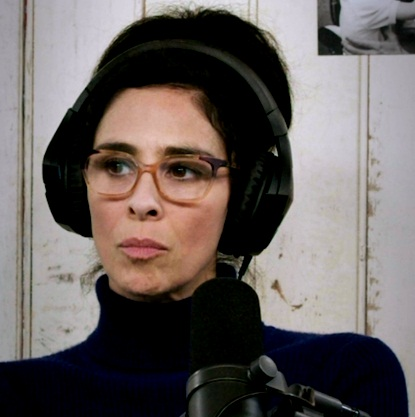
Comedian and author Sarah Silverman, along with authors Christopher Golden and Richard Kadrey, have sued Sam Altman-run OpenAI and Mark Zuckerberg-owned Meta over dual claims of copyright infringement.
The lawsuits alleged that OpenAI’s ChatGPT and Meta’s LLaMA (a set of large language models) were trained on illegally-acquired datasets containing their works.
Their works were allegedly acquired from “shadow library” websites like Bibliotik, Library Genesis, Z-Library, and others, noting the books are “available in bulk via torrent systems,” reports The Verge.
“When ChatGPT is prompted, ChatGPT generates summaries of plaintiffs’ copyrighted works — something only possible if ChatGPT was trained on Plaintiffs’ copyrighted works,” the lawsuit claimed.
The lawsuit alleged that chatbot never bothered to “reproduce any of the copyright management information Plaintiffs included with their published works.”
In a separate lawsuit against Meta, it alleged the authors’ books were accessible in datasets Meta used to train its LLaMA models.
“Many of Plaintiffs’ copyrighted books appear in the dataset that Meta has admitted to using to train LLaMA,” it read.
Silverman owns a registered copyright in one book, called The Bedwetter while Golden owns registered copyrights in several books, including Ararat.
Kadrey owns registered copyrights in several books, including ‘Sandman Slim’.
In both lawsuits, the authors said that they “did not consent to the use of their copyrighted books as training material” for the companies’ AI models.
Each lawsuit contains six counts of copyright violations, negligence, unjust enrichment, and unfair competition.
The authors are looking for statutory damages, restitution of profits, and more.
Meta or OpenAI did not comment on the lawsuits.
The suits alleges, among other things, that OpenAI’s ChatGPT and Meta’s LLaMA were trained on illegally-acquired datasets containing their works, which they say were acquired from “shadow library” websites like Bibliotik, Library Genesis, Z-Library, and others, noting the books are “available in bulk via torrent systems”.